An AI leadership coach that turns advice into a plan you can track
WorkBuddy is a full-stack coaching platform I designed and built end to end. A manager describes a real workplace challenge, talks it through with an AI coach named Simon, and gets back a structured plan with checklists, habits, and check-ins instead of a wall of chat text.
Overview
Users create challenges with a timeline and success criteria, such as improving retention on a team with low survey scores. Each challenge has its own coaching conversation with Simon, who is grounded in a curated library of leadership frameworks and, when the user uploads them, in the organization’s own documents: survey exports, turnover reports, and policies.
When a user asks for a plan, Simon stops answering in prose and produces a solution outline: phases with a purpose and timeframe, one-off checklist items, daily or weekly habits with streaks, and reflective check-in prompts. Progress on the outline rolls up to the challenge and to the dashboard.
The platform today
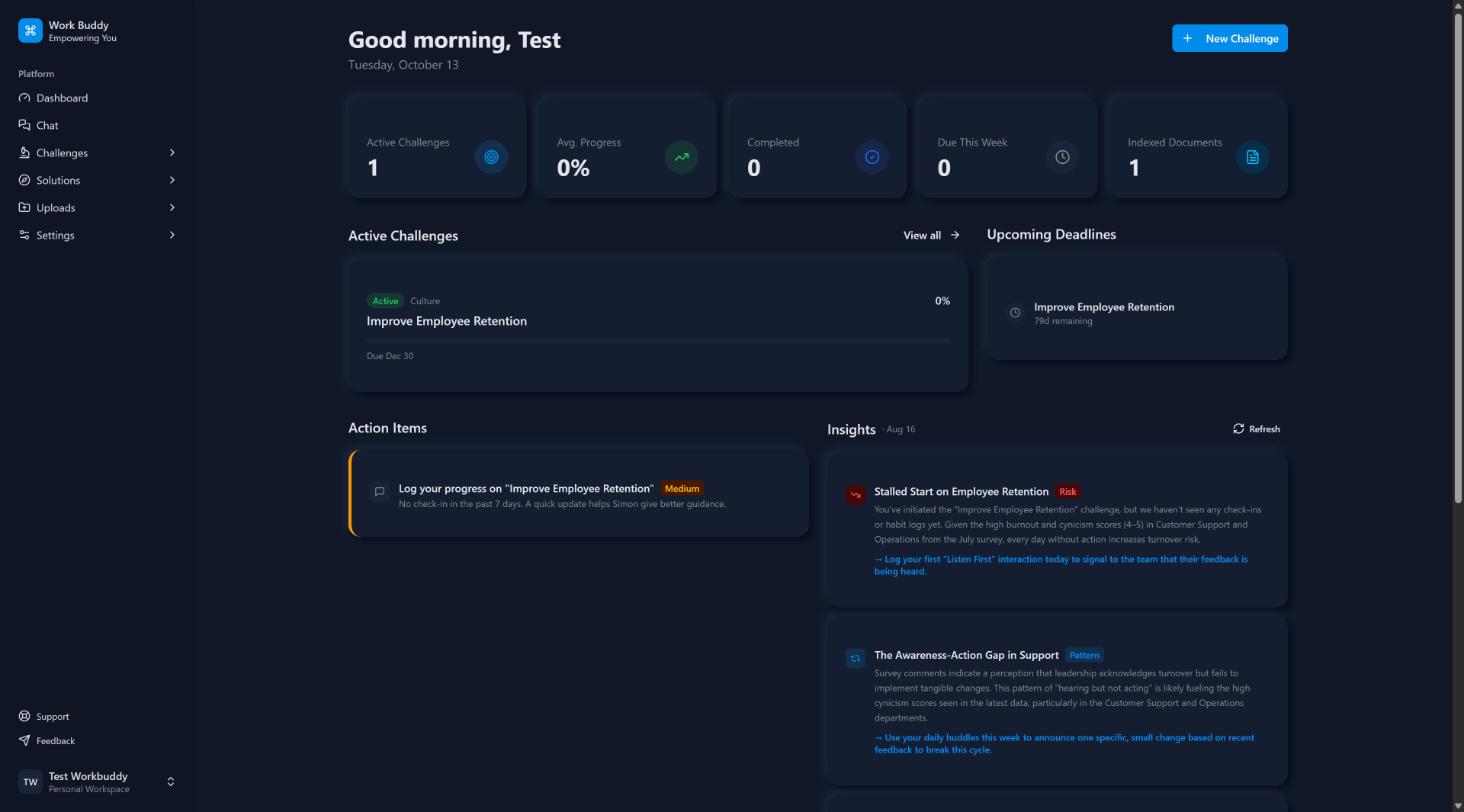 DashboardChallenge stats, rules-based action items, and AI-generated insights
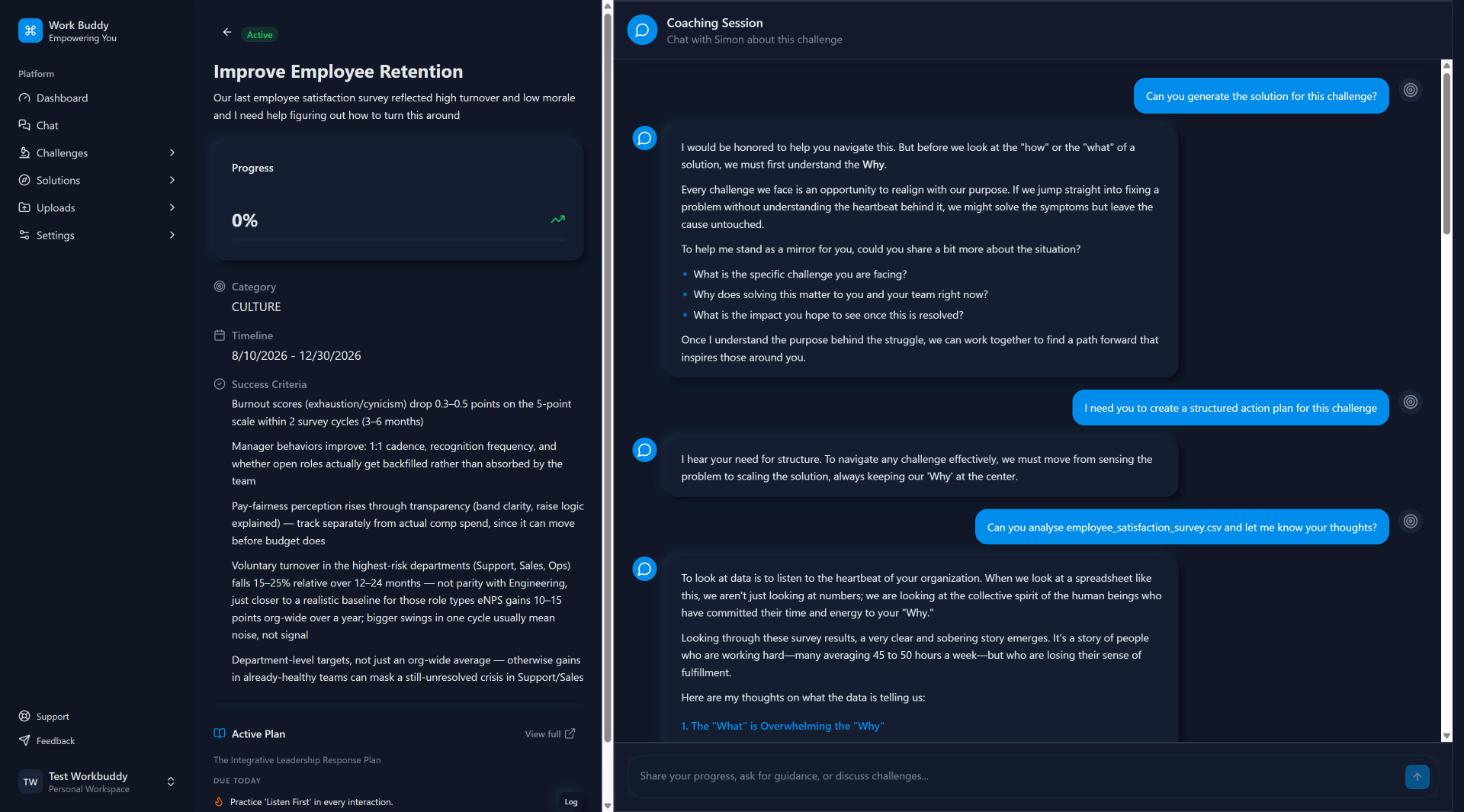 ChallengeSuccess criteria beside a streaming coaching session with Simon
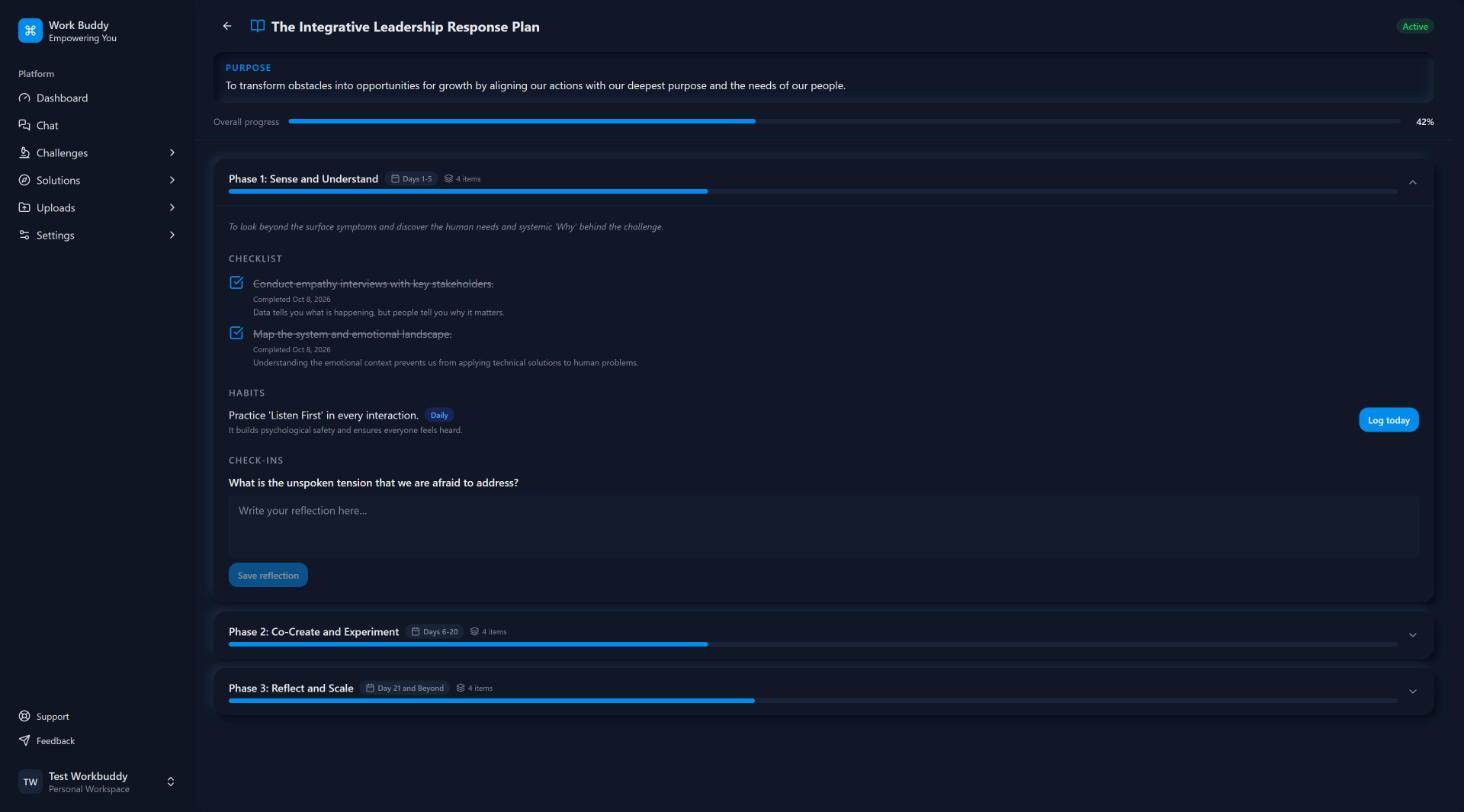 Solution outlinePhases with checklists, habits, and check-ins that drive progress
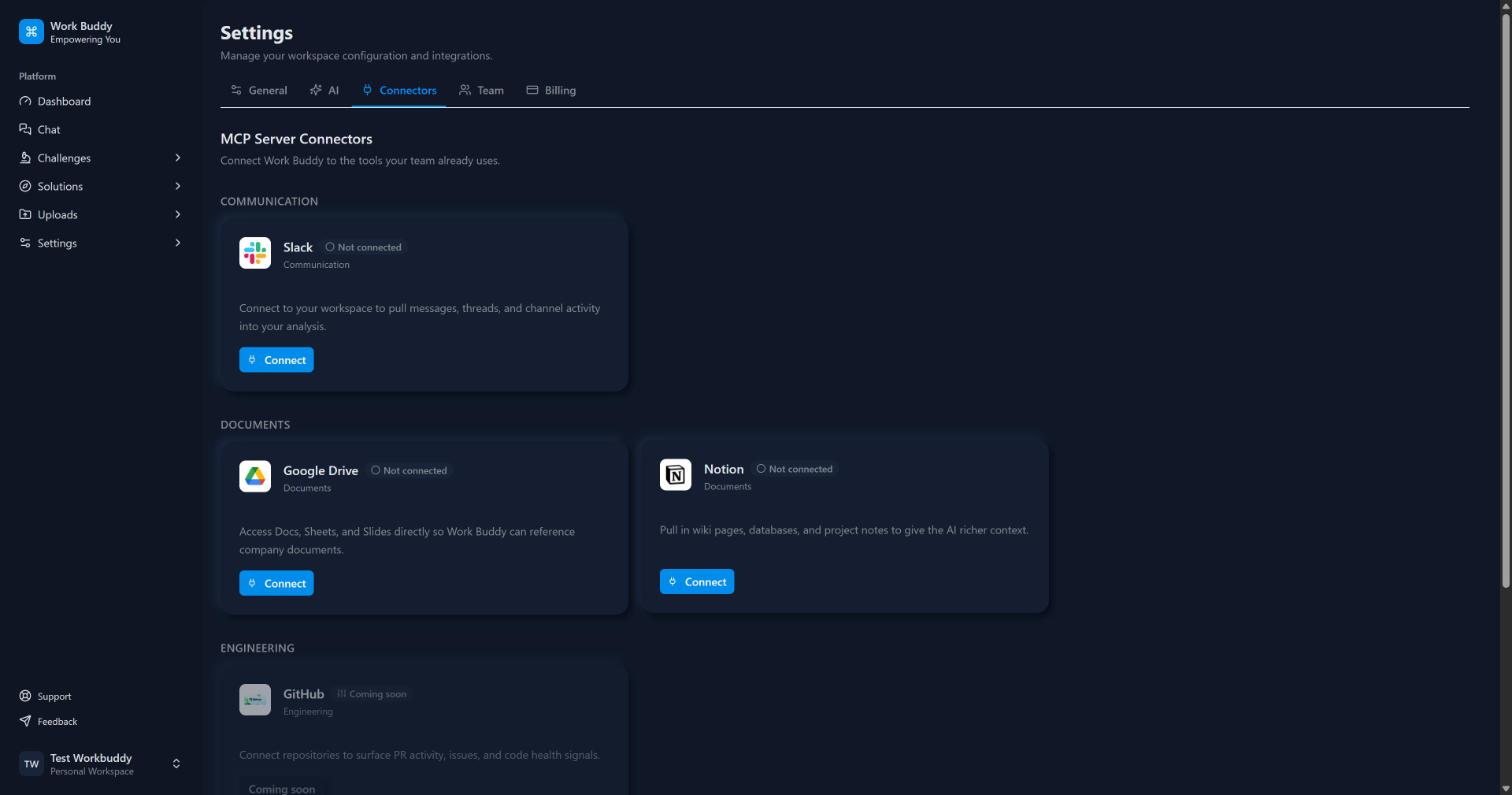 Connectors (planned)Interface for MCP connectors; the integrations are not wired up yet
Architecture
Three independently deployable TypeScript services with strict ownership rules. The API service is the only one that touches PostgreSQL. The agent service is the only one that calls the LLM or the vector store, and it reaches the database only through internal endpoints protected by a service token. The browser never talks to the agent directly.
Web UI
React, Vite, and Tailwind with shadcn/ui primitives. A token-based design system with shared status and progress components, built to pass a WCAG AA contrast audit in light and dark modes.
API service
Express and Prisma on PostgreSQL. Owns auth, challenges, conversations, outlines, documents, and organizations, with ownership checks on user data. Proxies AI calls and keeps the user’s message if the agent is down.
Agent service
Prompt building, retrieval, embeddings, and Gemini calls. Runs intent classification, knowledge search, conversation search, and document search in parallel before each reply.
Vector store
ChromaDB with separate collections for the curated knowledge base, conversation memory, insights, and user documents, accessed through an adapter so it can be swapped for pgvector later.
Engineering highlights
Structured plans from a chat model
A two-stage trigger decides when Simon should produce a plan: an embedding-similarity signal against fixed example phrases, then the model’s own judgment. The reply is a discriminated union, either conversation or outline, and every outline is validated before it is saved. Invalid output falls back to a normal reply.
Streaming that knows when not to stream
Replies stream over server-sent events from the agent, through the API, to the browser. The agent inspects the first characters of each response: prose is streamed token by token, while a JSON outline is buffered, parsed, and delivered as a finished card.
Document ingestion pipeline
PDF, DOCX, CSV, Markdown, and text uploads go through parse, chunk, embed, and store stages. CSV rows keep their column headers in every chunk. Ingestion runs in the background with a status lifecycle the UI polls, and deleting a document removes its vectors too.
Tenant-scoped retrieval
Uploaded documents live in their own collection and every chunk carries its organization ID, so retrieval is filtered per tenant without a database round trip. Retrieved passages are labeled by source in the prompt, so Simon can tell a leadership framework from the user’s own survey data.
Insights by tool calling
Dashboard insights come from an agent loop: the model calls tools to fetch challenges, recent check-ins, habit logs, past insights, and relevant document passages, then returns typed insight cards with a suggested next step.
Action items without an LLM
Not everything needs a model. Overdue, due-soon, stale check-in, and behind-schedule items are computed server-side from plain rules over existing data, prioritized and capped.
Deep dive: diagnosing RAG poisoning
Partway through development, Simon’s replies became steadily more verbose and philosophical. Every answer opened with sweeping motivational statements, whatever the question. I traced it to an architectural mistake: the persona documents (voice guidelines, behavioral commitments, coaching principles) had been ingested into ChromaDB alongside the knowledge base. Semantic search kept retrieving them as “relevant context” and injecting them on top of a system prompt that already contained the same instructions, so the effect compounded.
The fix was to enforce a boundary between who the agent is, which belongs in the system prompt only, and what the agent knows, which belongs in the vector store. I removed persona documents from ingestion, added a category filter in retrieval as a second guard, and rewrote the prompt in plainer language. That boundary now shapes later work: classifier examples are hardcoded constants, and user documents go in a separate collection from curated knowledge.
Where it stands
I work from a living specification. Each phase is written up with its scope, acceptance criteria, and what is deliberately out of scope before I build it.
- BuiltAuth, challenges, coaching chat with streaming, and the dashboard
- BuiltSolution outlines with checklists, habit streaks, check-ins, and weighted progress
- BuiltDocument ingestion and retrieval over uploaded files
- BuiltComputed action items and AI-generated insights
- In progressOrganization workspaces with roles, invite tokens, and team settings
- PlannedMCP connectors for Slack, Google Drive, and Notion
What I learned
- RAG systems degrade quietly when agent identity and retrievable knowledge share a store. Persona belongs in the system prompt, never in the vector index.
- Treat model output as untrusted input. A typed contract, validation, and a safe fallback matter more than a clever prompt.
- Streaming and structured output pull in different directions. Deciding early in a response which one it is keeps the chat responsive without showing users raw JSON.
- Put the tenancy key on the data itself. Filtering vectors by organization at query time is simpler and safer than joining back to the database on the hot path.